AI Compute Is Becoming the New Oil
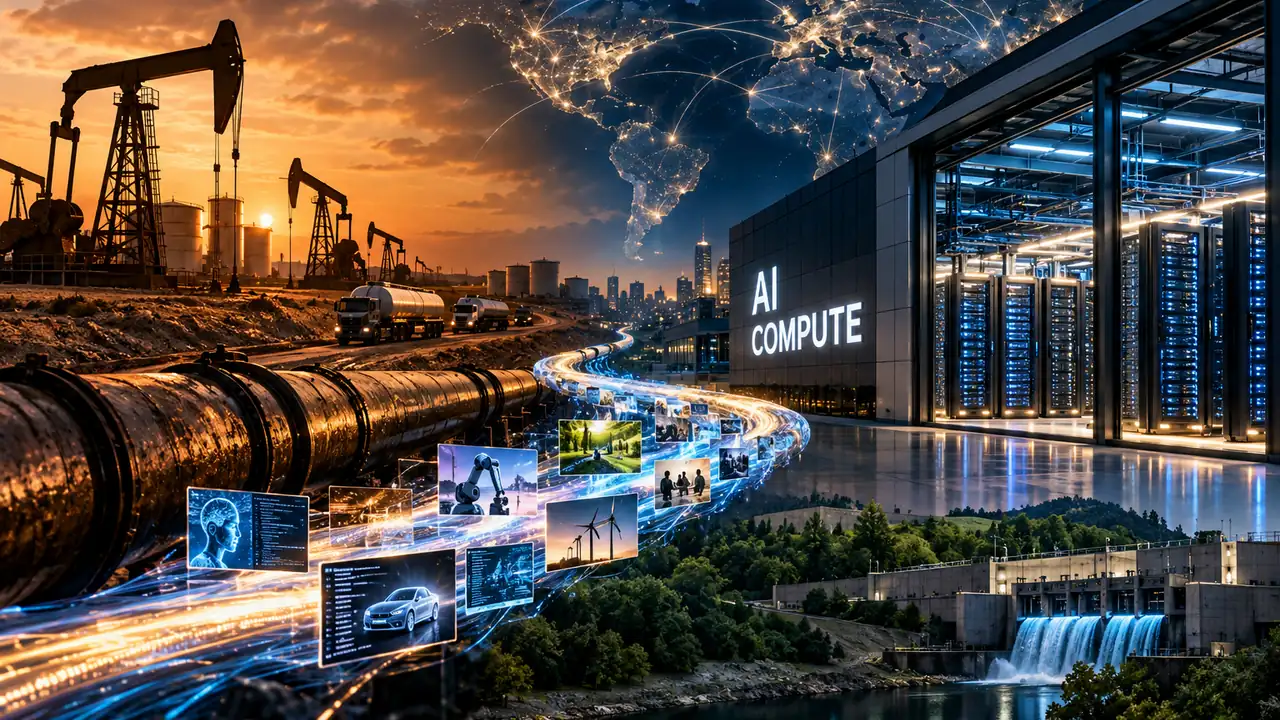
For years, the biggest conversation around artificial intelligence was about models.
Which model is smarter?
Which one can reason better?
Which one writes better code?
That conversation is slowly changing.
The next important question is becoming much more physical:
Where will all the computing power needed to run these AI systems come from?
AI may look like software, but behind every AI model is a large amount of physical infrastructure: chips, servers, networking equipment, data centers and electricity.
And that infrastructure is becoming one of the most valuable resources in technology.
This is why the phrase “compute is the new oil” is starting to make more sense.
Not because GPUs are literally replacing oil, but because access to computing power is becoming a fundamental requirement for the AI economy.
What exactly is “compute”?
In simple terms, compute is the amount of computing work a machine can perform.
Your laptop has compute.
Your phone has compute.
A cloud server has compute.
But modern AI systems need computing power on a completely different scale.
Training a large AI model involves performing enormous numbers of calculations repeatedly across thousands of processors.
The same thing happens after the model is trained.
Every time someone asks an AI system a question, generates an image, creates a video, writes code or asks an AI agent to perform a task, computers somewhere have to process that request.
Put simply, compute is essentially the amount of work computer chips can perform, while the size of an AI computing installation is often described in terms of how much hardware and power can be kept running at once.
So when we talk about AI getting bigger, we are also talking about the infrastructure required to support it getting bigger.
And that is where things become interesting.
AI needs more than just better chips
It is easy to look at an NVIDIA GPU and think the problem is simply manufacturing enough GPUs.
It isn’t.
A modern AI data center is a chain of dependencies.
You need advanced processors.
You need high-speed memory.
You need networking equipment to connect thousands of processors.
You need storage capable of feeding those processors with data.
You need cooling.
You need buildings designed for extremely high power densities.
And, most importantly, you need electricity.
If one of those pieces is missing, the GPUs cannot do much.
This is why the AI infrastructure race has moved beyond the chip itself.
Research from Omdia points to constraints across high-bandwidth memory, advanced packaging and semiconductor manufacturing capacity. TrendForce has similarly reported pressure on advanced packaging and leading-edge chip capacity as AI demand continues to grow.
In other words, the world isn’t simply trying to manufacture more AI chips.
It is trying to build an entire industrial system around them.
The surprising part: we may already have more compute than we are using
This is one of the most interesting developments happening right now.
At the same time that AI companies complain about not having enough computing capacity, some existing computing resources are sitting unused.
The reason is fairly simple.
AI workloads are not constant.
A company may need a huge amount of computing power while training a model. Once that training run finishes, some of that hardware may not be needed at the same intensity.
The hardware still exists.
The data center still exists.
The electricity connection still exists.
But the computing capacity may be sitting idle.
That is the problem the newly announced National Compute Grid is trying to address.
The initiative, announced on October 7, aims to connect computing resources from different sources and make unused capacity easier to access through a shared scheduling system. The idea is straightforward: before building another enormous data center, make better use of the infrastructure that already exists.
This is an important shift in thinking.
The solution to the compute shortage isn’t necessarily:
Build more.
Sometimes it can be:
Use what already exists more efficiently.
Why are companies spending so much money on compute?
Because AI usage is changing.
A simple chatbot request doesn’t necessarily require an enormous amount of computing power.
But newer AI systems increasingly do more work before producing an answer.
They may reason through a problem, use tools, search information, write and execute code, check their own work and then continue.
That means one user request can turn into many computing operations.
The International Energy Agency has highlighted the same trend from the energy side. Newer AI applications such as video generation, reasoning and agentic tasks can require dramatically more energy than simple text generation.
So there are actually two things happening simultaneously:
AI is being used by more people.
And each AI interaction can become more computationally expensive.
That combination creates enormous demand for infrastructure.
This is why AI companies are signing huge compute deals
Look at what the major AI companies are doing.
Anthropic has signed agreements covering multiple gigawatts of computing capacity.
Its agreement with Amazon includes up to 5 gigawatts of capacity and more than $100 billion in planned spending on AWS technologies over ten years.
Anthropic has also announced major arrangements involving Google, Broadcom, Microsoft, NVIDIA and SpaceX.
Its SpaceX agreement alone gives Anthropic access to more than 300 megawatts of new capacity and more than 220,000 NVIDIA GPUs.
OpenAI is doing something similar.
Its Stargate infrastructure program originally targeted 10 gigawatts of AI infrastructure in the United States by 2029. OpenAI says it has already passed that milestone in contracted capacity as it continues adding capacity.
Microsoft announced a new Texas data center campus expected to add approximately 2 gigawatts of capacity.
Meta’s Hyperion project in Louisiana is planned to reach 5 gigawatts and represents an investment of more than $50 billion.
These numbers are difficult to visualize.
A gigawatt is not a normal cloud-computing measurement that most people encounter.
It is a measurement of power.
And that tells us something important.
AI infrastructure is increasingly being planned like an industrial project rather than a traditional software product.
Electricity is becoming part of the AI story
This may be the most overlooked part.
People talk about GPUs.
They talk about NVIDIA.
They talk about data centers.
But all those machines need electricity.
And AI data centers are putting significant pressure on power infrastructure.
The IEA estimates that global data-center electricity consumption could roughly double from about 485 TWh in 2025 to around 950 TWh by 2030. Electricity consumption from AI-focused data centers is expected to grow even faster.
Gartner estimates global data-center electricity consumption will reach 565 TWh in 2026, up 26% from 2025. It also expects AI-optimized servers to account for 31% of data-center power consumption this year.
The United States is seeing the impact as well.
The U.S. Energy Information Administration expects American electricity demand to reach record levels in both 2026 and 2027, with data centers serving AI and cryptocurrency workloads among the major drivers.
So the AI race is also becoming an energy race.
The company that has access to GPUs but not enough electricity has a problem.
The company that has electricity but cannot obtain the required chips has a problem.
And the company that has both still needs a data center capable of putting everything together.
Data centers are starting to look more like power plants
This is another major change.
Traditional data centers were primarily designed around IT equipment.
AI data centers have much higher power requirements.
The IEA says the power density of AI servers increased roughly elevenfold between 2020 and 2025 and could increase another fourfold by 2027.
That creates problems with:
- electricity delivery
- cooling
- transformers
- transmission infrastructure
- land
- construction
- water
- reliability
This is why companies are increasingly building or securing their own energy infrastructure.
Microsoft’s new Pecos, Texas campus, for example, is planned with dedicated energy infrastructure, including an onsite natural-gas facility at launch. Microsoft says the arrangement is intended to bring power online for the campus without taking the same demand from the existing public grid.
The important point is not whether natural gas, nuclear or renewables ultimately win.
The important point is that energy availability has become part of the AI infrastructure strategy.
And then there is the GPU itself
NVIDIA has become the most visible company in this story because its GPUs are central to much of today’s AI infrastructure.
But the real story is larger than NVIDIA.
Google has TPUs.
Amazon has Trainium.
Meta is developing its own MTIA chips.
Other companies are developing specialized processors.
The reason is simple: if compute becomes a major operating expense, companies have a strong incentive to make that compute more efficient.
Google’s latest AI infrastructure, for example, includes specialized TPU systems designed for different workloads. Google says its latest TPU systems can be connected at enormous scale, while specialized inference hardware is designed to improve performance and cost efficiency for AI applications.
Meta is taking a similar approach with its own MTIA chips, designed specifically around its workloads.
The future therefore probably won’t be one giant market where everybody uses the same GPU.
It will be a mixture of GPUs, custom chips and different types of computing infrastructure.
The common resource underneath all of them is compute.
Compute is becoming something companies need to buy
This is where the comparison with oil becomes much more interesting.
A few years ago, a company building an AI product could largely think about computing as another cloud bill.
Now, for companies operating AI at serious scale, compute availability can affect the entire business.
How much does it cost?
How much capacity can we get?
When will it be available?
Which hardware should we use?
How long should we commit to it?
Should we buy hardware?
Should we rent it?
Should we use a cloud provider?
Should we use specialized GPU providers?
These are increasingly financial and strategic decisions.
GPU rental prices can also move significantly when supply gets tight.
During earlier periods of severe shortage, rental prices for NVIDIA H100 GPUs reached very high levels before falling as supply improved. The volatility is one reason financial markets have started paying attention to compute pricing.
The biggest sign yet: compute is getting a futures market
This is where the “new oil” comparison stops sounding like marketing.
CME Group has announced compute futures tied to NVIDIA H100 and B200 rental-price indexes. The listing, first planned for October 5, 2026, was pushed back while the futures regulator reviewed the contracts.
A contract represents a month’s worth of GPU capacity.
The purpose is similar to what futures markets do in other industries: give businesses a way to manage uncertainty around future prices.
Think about what that means.
A few years ago, very few people would have imagined that someone would need to hedge the future price of computing power.
Now there is an actual financial market being built around it.
CME lists the contracts among its energy products and describes them as a new way to hedge AI risks.
That doesn’t mean compute has suddenly become identical to oil.
It hasn’t.
But the comparison is becoming useful because both are examples of a resource that becomes extremely important when an entire economy depends on it.
There is another difference between compute and oil
There is one important reason I wouldn’t take the comparison too literally.
Oil is a physical commodity that gets consumed.
Compute is different.
The physical hardware doesn’t disappear after performing a calculation.
A GPU can run another job tomorrow.
That means compute can become more valuable through better utilization.
This is why companies trying to optimize existing data centers are becoming interesting.
One startup, Turba Labs, is specifically targeting this problem by trying to increase the amount of useful computing work that can be extracted from existing infrastructure rather than simply constructing more data centers.
And that brings us back to the National Compute Grid.
There may be enormous value in making existing compute easier to share.
The real scarce resource may eventually be access
There is an important distinction here.
The world doesn’t necessarily have zero computing power.
The problem is that the computing power isn’t always available:
- in the right location
- at the right time
- on the right hardware
- at the right price
- with enough electricity
- with enough networking
- for the workload that needs it
This is a much more complicated form of scarcity.
Imagine a city with plenty of electricity-generating capacity but not enough transmission lines to deliver it where demand exists.
The electricity exists.
But it isn’t necessarily useful to everyone who needs it.
Compute can have a similar problem.
A GPU sitting unused in one facility doesn’t automatically solve the shortage faced by a researcher or company somewhere else.
That is why scheduling, marketplaces, standard pricing and shared infrastructure are becoming increasingly important.
India is also building its own compute base
This isn’t only an American story.
India has been building domestic AI computing capacity through the IndiaAI Mission.
Government figures published in 2026 said more than 38,000 GPUs had already been onboarded through empanelled service providers and data centers, with additional capacity planned. Reports of the same statement to Parliament put the average subsidized access price at around 65 rupees per GPU-hour.
That is important because access to compute can influence who gets to build AI products.
If only the largest technology companies can afford the necessary infrastructure, AI development becomes concentrated among a small number of companies.
If compute becomes easier for startups, universities, researchers and smaller businesses to access, more experimentation becomes possible.
That is one of the reasons compute infrastructure is becoming a strategic issue for countries as well as companies.
The next battle may be about efficiency
There is a temptation to think the AI future simply means building bigger and bigger data centers.
But that cannot continue forever without consequences.
More hardware means more electricity.
More electricity means more infrastructure.
More infrastructure means more capital.
And all of it has to eventually generate enough economic value to justify the investment.
This is why efficiency is becoming just as important as raw performance.
A chip that is twice as fast is useful.
A chip that performs the same work using half the electricity can be just as valuable.
A data center that gets significantly more work from the same hardware can effectively create new compute capacity without buying another building full of machines.
That is an important part of the story that often gets lost when AI infrastructure is discussed.
The future isn’t only about more compute.
It is also about better use of compute.
So, is compute really the new oil?
In one sense, yes.
Compute is becoming a foundational input for the AI economy.
AI companies need it.
Cloud providers sell it.
Chip manufacturers build hardware for it.
Data centers consume enormous amounts of electricity to provide it.
Investors finance it.
Governments are trying to secure it.
And financial markets are beginning to create standardized ways of pricing and hedging it.
That is a lot more than simply saying GPUs are expensive.
But there is an important difference.
Oil powered factories, transportation and modern industry because it was burned and consumed.
Compute doesn’t disappear when a calculation is finished.
A better way to think about it may be this:
Compute is becoming the industrial capacity behind intelligence.
The AI model is what people see.
The compute is what makes it possible.
And as AI moves from answering questions to writing software, analyzing businesses, operating machines, generating video, performing research and running autonomous workflows, the amount of computing required will increasingly become a business constraint.
That is why the next phase of the AI race may not be decided only by who builds the smartest model.
It may also be decided by who can secure enough compute, enough electricity, enough hardware and enough infrastructure, and use all of it efficiently.
The AI revolution may look digital on the screen.
Underneath the screen, it is becoming an industrial race.