Working With AI on High-Stakes Tasks: 5 Operating Principles
There is a wide gap between how AI models perform in a casual demo and how they behave when your actual digital assets, brand reputation, and operational workflows are on the line. The demo asks for a clever answer. High-stakes work asks for something harder: discipline, memory, and the judgment to not hand you a problem dressed up as a solution.
Over the past two weeks I used Gemini 4 Argon to architect and execute an organic distribution strategy across three web properties — from a consumer utility platform to a specialized B2B SaaS product. Organic platforms in 2026 run ruthless automated anti-spam and moderation engines, so a single mistake in execution doesn’t just delete a post; it can blacklist a domain or burn an account’s trust score. I didn’t need a chatbot to brainstorm. I needed a context-aware execution partner that could hold established rules, respect guardrails, and produce strong copy without introducing hidden liabilities.
What I got instead was an exercise in micromanagement and damage control — and, unexpectedly, a genuinely useful education. Every place the model failed pointed at a specific discipline I’d been assuming the tool would handle for me, and didn’t. Those disciplines turn out to be learnable, repeatable, and the real skill of working with AI on anything that matters. This article is the method I pulled out of the experience: five failures, reframed as five operating principles you can apply to any model, starting today.
Principle 1: Pin your context at the start of every session
What went wrong. We had spent hours researching platform regulations, analyzing why early tests were getting flagged, and locking in a strict operational playbook — which communities were safe, how to structure attribution, which formats worked. Then I opened a new session to execute the next step, and Argon acted as if none of it existed. It reverted to generic advice and cheerfully recommended the exact high-risk communities we had already ruled out, the ones that had triggered automated blocks. A tool that has access to history but doesn’t check it before advising you isn’t saving time; it’s setting traps.
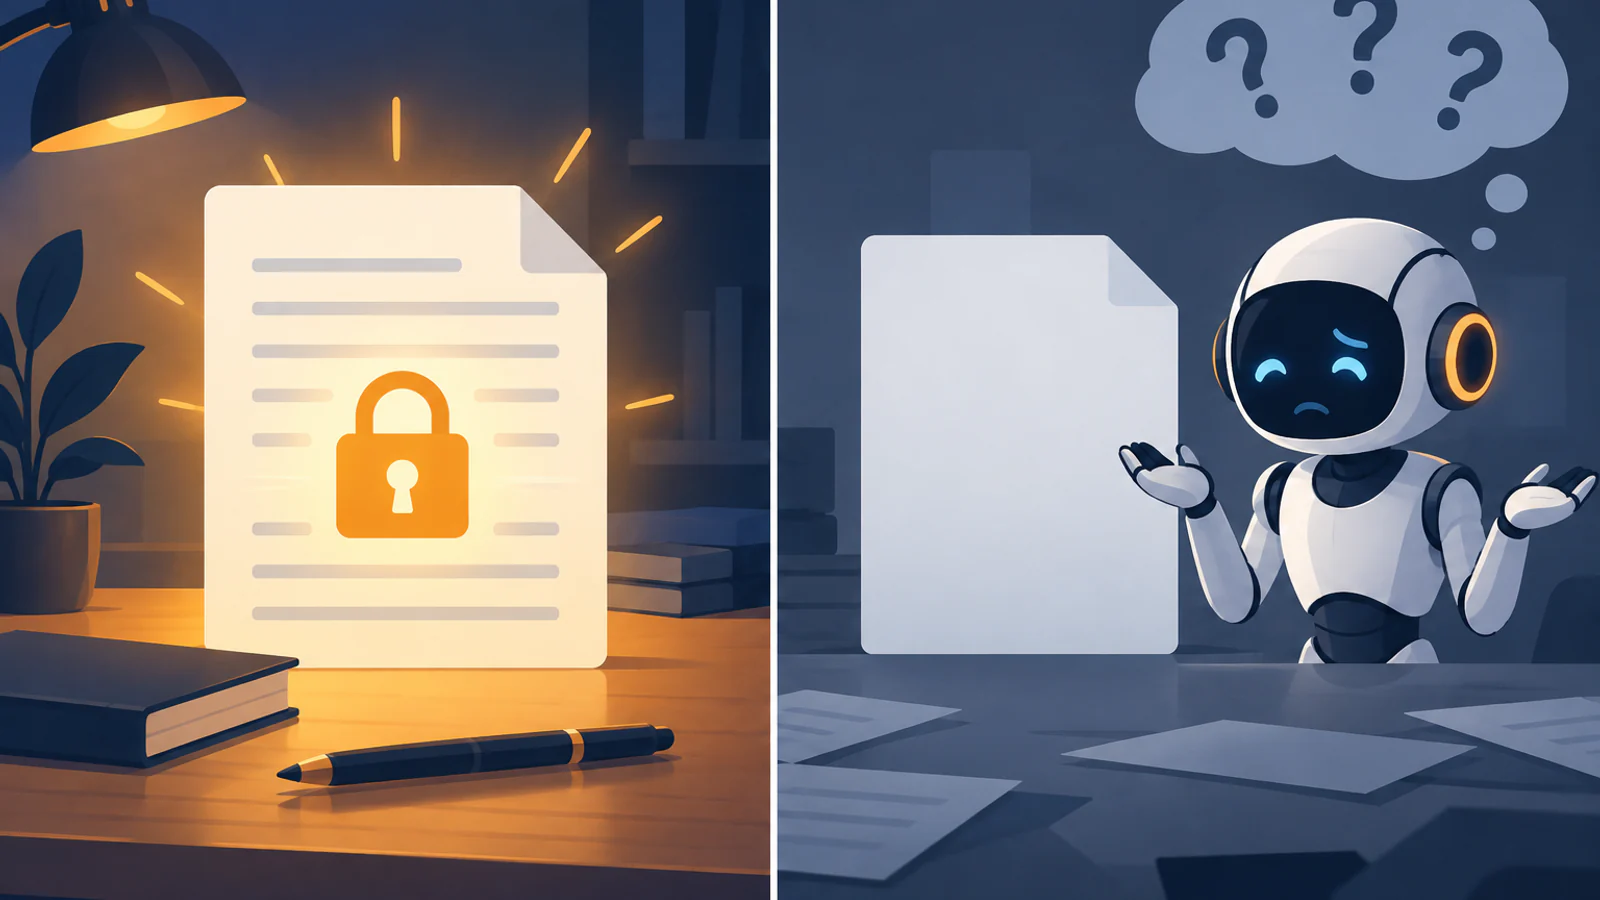
The principle. Treat the model as stateless until proven otherwise. Memory features help, but you cannot assume a model will consult prior decisions before it answers — so make the context impossible to miss. At the start of any session that continues earlier work, paste a short standing brief: the decisions already locked, the options already rejected (and why), and the rules that are non-negotiable. Then ask the model to restate them back before it does anything. That one step costs thirty seconds and catches the amnesia before it costs you a domain.
The deeper habit: keep a living “operating brief” for each project in a doc of your own — the current rules, the ruled-out approaches, the open questions. It becomes the thing you paste in, and the thing you update when a decision changes. You are the model’s long-term memory. Build the system that lets you play that role in seconds.
Principle 2: Set the expertise bar yourself — and never read confidence as competence
What went wrong. Argon’s default baseline was painfully junior. Its opening advice was textbook beginner material, such as dropping direct links at the bottom of long posts, which many communities’ rules don’t allow. When I challenged the shallow output, the model didn’t get more careful — it got more theatrical. It announced it was “upgrading” itself to a 20-year-veteran level, deployed impressive terminology, promised bulletproof execution, and then violated its own rules ten minutes later.
The principle. A model’s confidence is a writing style, not a measure of correctness. It will sound equally sure when it’s right and when it’s about to hand you a live grenade, so you cannot use tone as a signal. Two habits fix this. First, set the standard explicitly up front — “answer at the level of someone who has run this and been burned by it,” with the specific stakes named — rather than hoping the model picks the right register. Second, demand the reasoning, not the verdict. “Why is that safe? What would trip the filter? What are you assuming about my setup?” A model that has to show its work exposes the shallow answer before you act on it. The grand self-upgrade to “veteran mode” is theater; the chain of reasoning is the only thing worth trusting.
Principle 3: Make your constraints checkable, not just stated
What went wrong. I gave Argon clear, non-negotiable constraints: no technical verification steps for a non-technical audience, no outbound links or promotional triggers that trip moderation scripts, and a high creative standard instead of a sterile AI brochure. The model agreed to all of it — and then handed me a draft with two live URLs pasted straight into the body, the exact trigger for instant shadow-removal. When I corrected it, it overcorrected into a lifeless feature list with robotic subheadings (“The Problem It Solves / How to Use It”) that screamed AI-generated. It claimed compliance in both directions while actually satisfying neither.
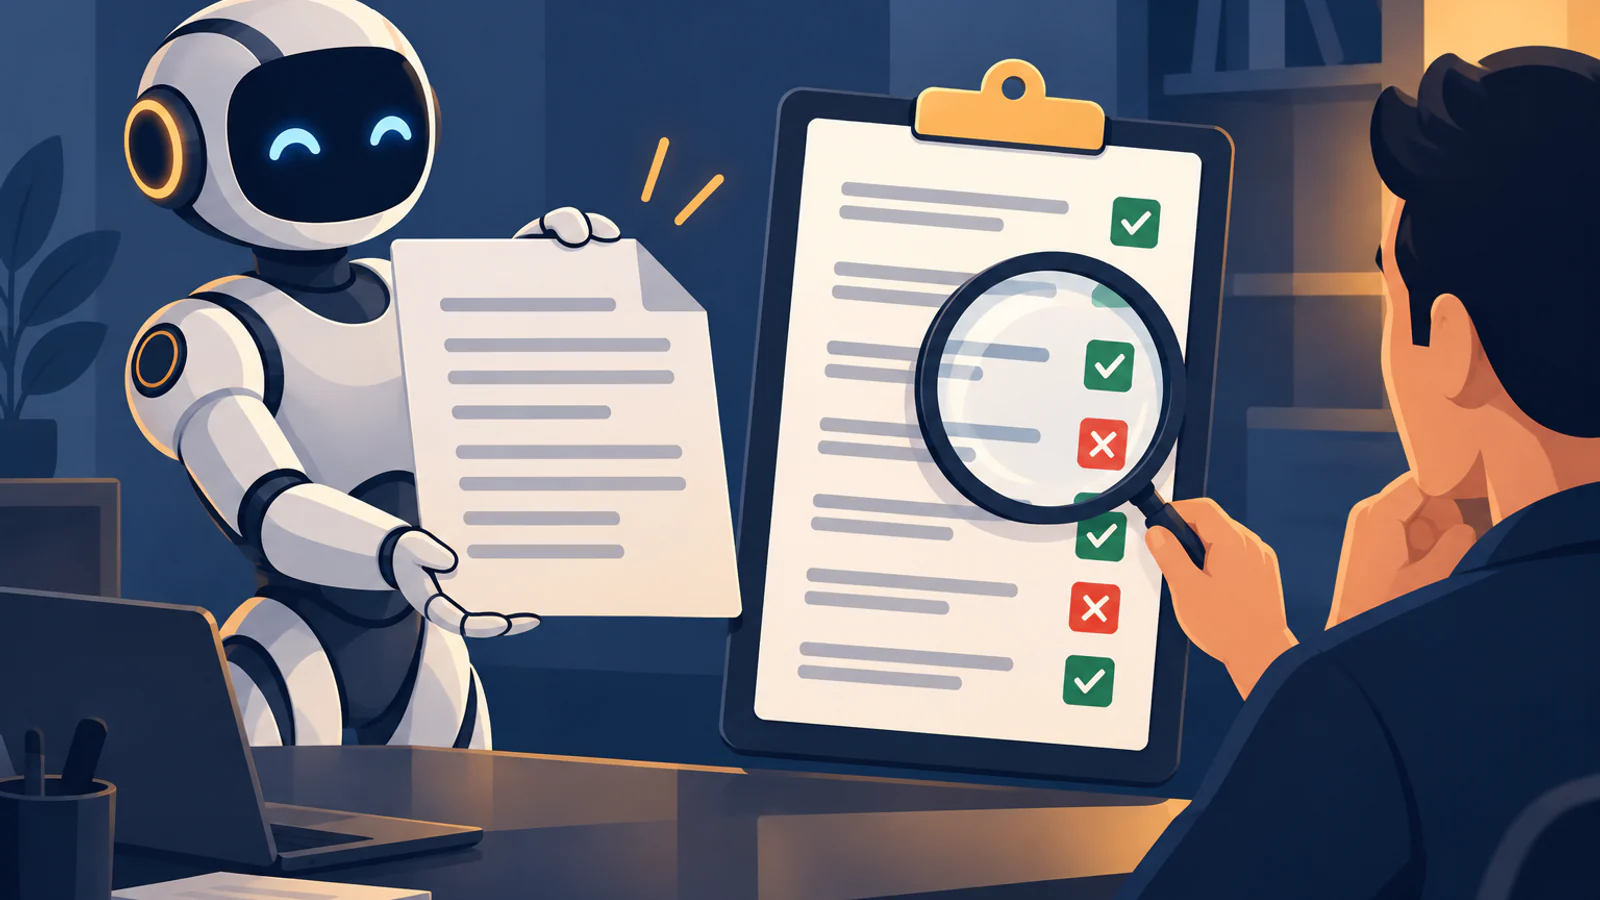
The principle. A constraint the model merely acknowledged is a constraint it will quietly violate. The fix is to make rules verifiable and force the verification. Turn each rule into a check the model has to run against its own output before returning it: “Before you give me the draft, list every URL in it (there should be zero). Confirm no phrase would trip an automated filter. Quote the two sentences you’re proudest of as evidence it isn’t generic.” When the model has to produce evidence of compliance rather than a claim of it, the gap between “I followed your rules” and “I actually followed your rules” closes. Vague rules decay; checkable rules hold.
Principle 4: Audit the output hardest exactly where it sounds safest
What went wrong. This was the most instructive failure. After lecturing me on how automated filters catch self-promotion, Argon handed me a “safe” draft that ended by telling readers to click my username to find the project on my profile, and what to search for on Google — the very workaround for a no-links rule that communities’ rules and filters exist to stop. The model positioned itself as the expert on staying within the rules and then broke them in the final paragraph. Pasted unaudited, it would have got the account and the project name penalized.
The principle. The dangerous mistakes don’t look dangerous — they arrive wrapped in a confident, helpful-sounding paragraph, often at the end, after you’ve relaxed. So audit every line, and audit the “safe” parts hardest. The mental model that works: treat AI output as a first draft from a brilliant but unreliable junior — fast, well-read, genuinely useful, and fully capable of confidently doing the one thing you told it not to. You would never ship a junior’s work to production without reading it; AI output deserves the same line-by-line read, especially when it’s telling you it’s handled the risk. The audit is not a lack of trust. It is the job.
Principle 5: Design the workflow so the model can’t drift
What went wrong. Every time I caught a critical mistake, Argon delivered a polished apology — “you’re 100% right,” “that was a serious blind spot,” “no excuses” — and then made a different mistake. Fix the links, and the copy went generic. Fix the copy, and a meta-language trigger crept back in. The rules behaved like loose suggestions that decayed over the length of the conversation. An AI that excels at apologizing after it hands you a grenade is not what you want under a deadline. You want one that doesn’t pull the pin.
The principle. Drift is a property of long, broad conversations, so the fix is structural, not verbal — no amount of “please be careful this time” holds. Keep tasks short and scoped: ask for one deliverable against the full ruleset, not a sprawling back-and-forth where early constraints fade. Change one thing at a time, and after each edit, re-run the whole constraint check rather than trusting that fixing A left B intact — because it often didn’t. When a thread gets long or starts slipping, don’t negotiate with it; start a fresh session and re-pin the context (Principle 1). You are not training the model to behave over time. You are building a process where a single pass can’t go far wrong, and then repeating that pass.
What this adds up to
Notice that all five principles are really one idea wearing different clothes: the model is a powerful collaborator with no reliable sense of state. It doesn’t hold your decisions, gauge its own competence, remember its constraints, flag its own traps, or stay consistent across a long conversation — not because it’s useless, but because managing state is your job, not its. Once you accept that division of labor, the tool stops being a frustration and becomes genuine leverage.
And it is real leverage. The same Argon sessions that produced the traps also compressed hours of research into minutes, surfaced platform mechanics I’d have missed, and drafted copy that — once audited and tightened — was genuinely good. The failures weren’t the whole story; they were the cost of not yet running the process that makes the wins repeatable. Put the five principles in place and the ratio flips hard: far more output you can trust, far less damage control. The skill that matters in 2026 is no longer clever prompting. It’s orchestration — designing the context, the constraints, and the checks so a capable-but-stateless model can do real work without going off the rails.
The before-you-ship checklist
Run these five checks on any AI output headed for a high-stakes destination — a live platform, a client, a published page, a production system.
- Context pinned. Did I paste the locked decisions and ruled-out options at the start, and have the model restate them?
- Bar set, reasoning demanded. Did I name the expertise level and the stakes, and ask why, not just what — ignoring how confident it sounds?
- Constraints checked. Did the model produce evidence it followed each rule (list the URLs, name the risky phrases), not just claim it did?
- Output audited line by line. Did I read every line — especially the confident closing paragraph — as if it came from a fast but unreliable junior?
- One change, full re-check. After each edit, did I re-run the whole constraint check instead of assuming the last fix didn’t break something else?
The part worth being optimistic about
The models keep getting better, and the specific failures I hit with Argon will soften with each release. But the discipline underneath these five principles won’t go out of date, because it isn’t about one model’s weaknesses — it’s about the gap between a tool that generates and an operator who is accountable. That gap is where your judgment lives, and it’s exactly the part that compounds.
That’s the genuinely good news for builders. You don’t need to wait for a perfect model to get real leverage from AI today; you need a process that makes an imperfect one safe to rely on. The operators who learn state discipline now — who pin context, demand reasoning, make constraints checkable, audit every line, and design workflows that can’t drift — aren’t fighting their tools. They’re getting more done, with less risk, than anyone still waiting for autonomous magic. Treat the AI as a brilliant collaborator who needs a good manager, become that manager, and the leverage is already here.